
Staff Writer
Published August 31, 2026 · Updated October 1, 2026last updated dates
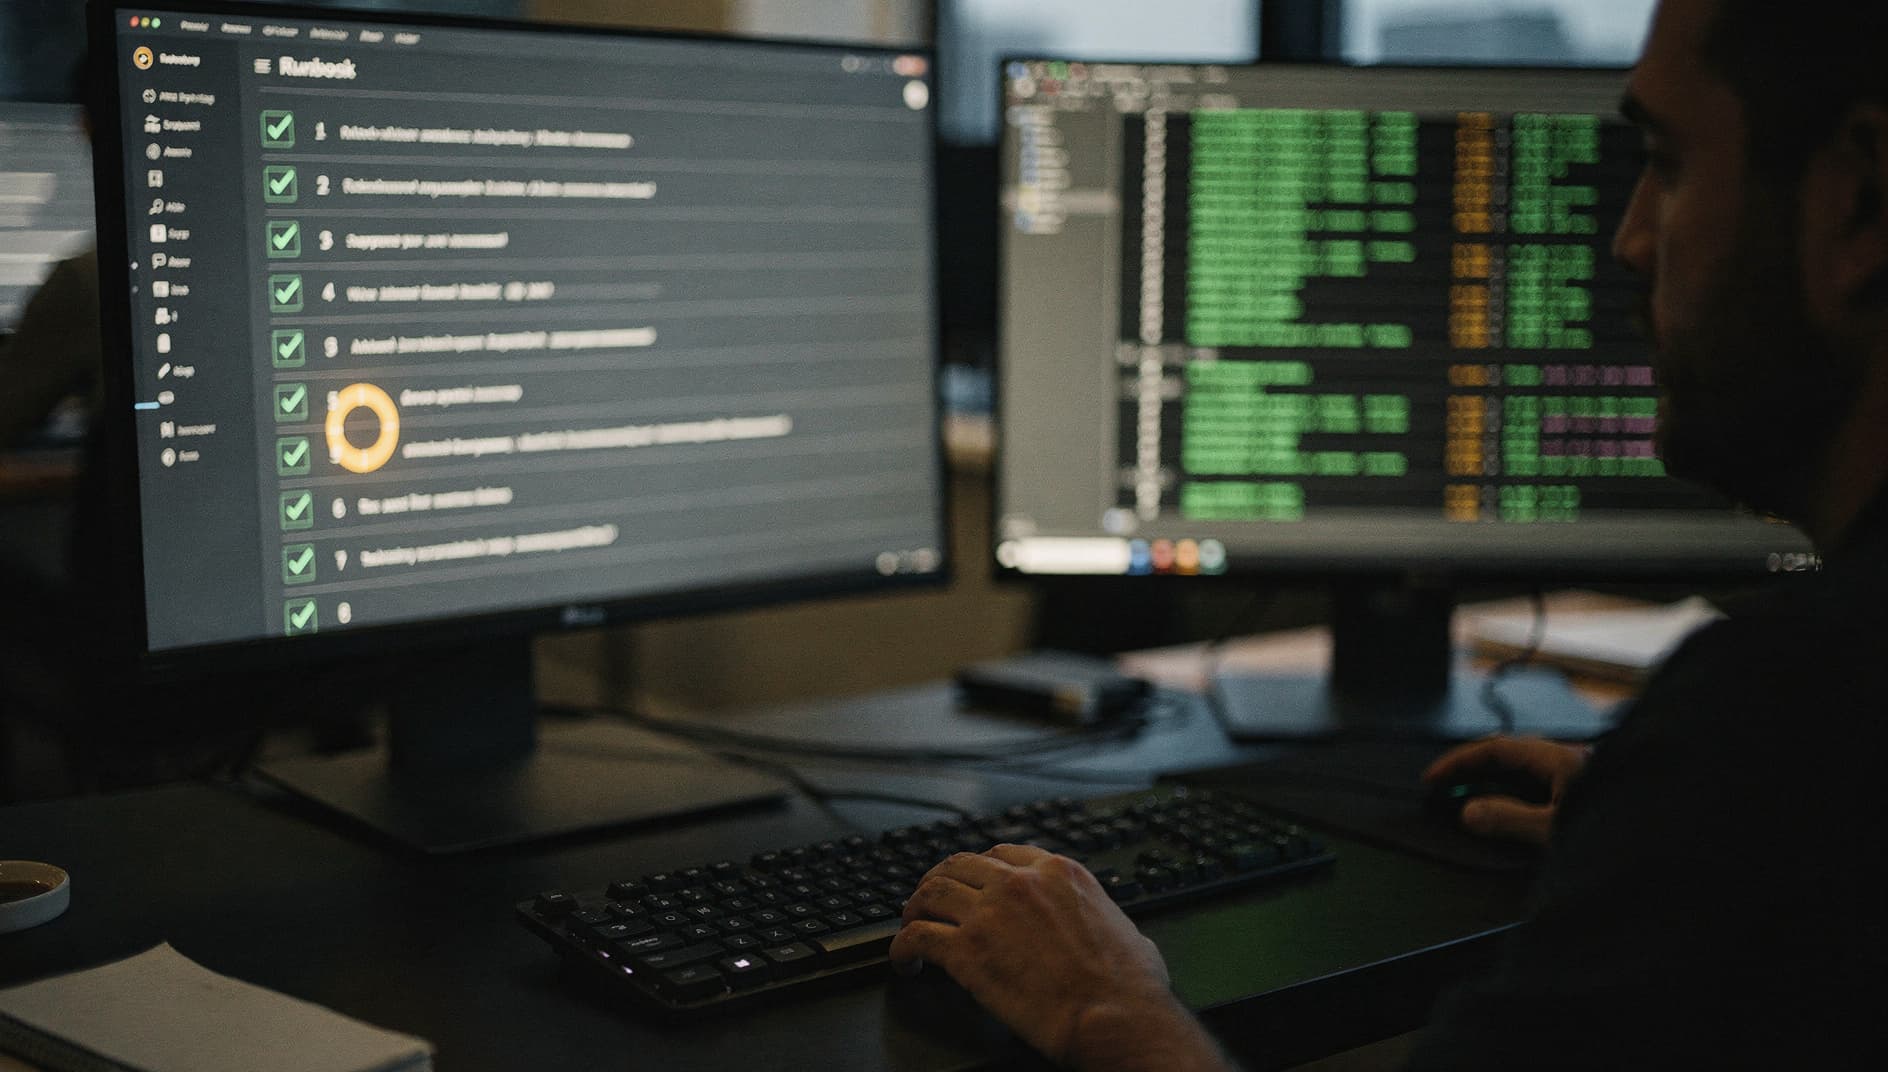
Your AI Agent Shouldn't Be Improvising Your Deploys
Give two AI agents the same ops task and you get two different results. That's fine for a landing page. It's a disaster for a deploy, and the fix is not a better model.
AI agents are stochastic, and that's the job description. Run the same task through the same agent twice and you get two different paths: steps in a different order, different shortcuts taken, different edge cases caught. Ask three agents to draft a landing page and you get three pages you can react to. The variance is the point.
Now ask an agent to provision a server, wire up a deploy, run a migration, or set up a cron job. There you don't want three interpretations. You want the same result every time, built the same way, byte for byte where it matters. Variance in creative work is a feature. In set-in-stone operational work it's a bug you pay for in incidents.
The pod that came out different every time
I run client-facing AI agent pods, and each one gets provisioned from a written checklist of about forty steps: infrastructure, credentials, integrations, the chat UI, health checks. For a while that checklist was prose. Every run, an agent read it and did its best.
Every pod came out different. Most were fine. Some quietly skipped a step nobody noticed until later. The worst one: the step that wires the chat UI so the client can actually see and select the model. It's invisible if you're not looking for it, and it makes the product dead on arrival for the client. We missed it on four pods in a row.
The root cause was structural. The checklist was prose, and an LLM was re-deriving it fresh on every run. Different agent, different ordering, different memory of which steps mattered. Somewhere in the middle of forty lines of English, a mandatory instruction decays into a suggestion.
The fix wasn't a louder prompt
We didn't try harder prompting, bigger context windows, or a more expensive model. We collapsed the checklist into runbook-as-code: a skill. A fixed, ordered catalog of steps. Idempotent, so a step that already ran doesn't run twice. Mandatory gates that refuse to report "done" while any step is unverified. Known failure modes baked into the exact commands, like "this command needs a --yes flag or it silently does nothing," the kind of detail you only learn by getting burned once.
Progress is persisted, so a failed run resumes at step twenty-three instead of restarting at step one. Tests assert byte-stable output and stable ordering. The whole thing is versioned like code, because it is code.
Result: identical pods every time. The "forgot to wire the model" failure is now impossible, because the run halts at a gate until that step verifies against a live client account. The agent became the operator of a deterministic engine: the procedure moved out of its head and into code, and its reasoning goes to the parts that are genuinely unexpected.
Why every framework converged on skills
This is why "skills" are showing up everywhere at once. Anthropic has Agent Skills. OpenAI ships skills. OpenClaw has a skill system. Hermes has skills. Different vendors, same shape: a versioned, executable procedure the model follows instead of re-deriving.
The concept is portable because the problem is universal. A multi-step workflow encoded as a skill runs the same whether the agent is a Telegram bot, a web agent, or a desktop agent. Write the procedure once and it works on any framework that supports skills. Your operational knowledge becomes an asset you own instead of something trapped in one vendor's prompting conventions.
The four rules I run by
- Sort your workflows into deterministic and stochastic. Deterministic means it must run the same way every time: provisioning, deploys, migrations, cron, config. Stochastic means it needs judgment: drafting, design, research, triage. Most teams blur the line and let the LLM do both. That blur is where the four-pods-in-a-row failure comes from.
- Deterministic work belongs in a skill or script: fixed order, idempotent, self-verifying. The model reasons about the novel parts and executes the known parts, not the other way around.
- Every scar is an assertion you haven't written yet. When a run burns you and someone writes "remember to do X," that's a deterministic check stored in institutional memory. Encode it as a line of code instead. Memory fades; an assert fires every time.
- Skills are the portable unit. Write the procedure once and it runs on any framework that supports skills, so your runbooks survive the framework wars.
The verification side of this connects to what I wrote about in Agile Is Broken for AI Agents: every "done" has to be a machine-checkable predicate, not a promise. A skill is where those predicates live.
What this means for you
If agents are doing real operational work for you, find the prose checklist they re-derive every run. It's the one producing a different result each time. Collapse it into a skill with ordered steps, idempotency, and gates that verify against the real world before reporting done.
You're not removing randomness from your agents, and you wouldn't want to. Randomness stays. You just aim it at the problems that need judgment. Everything else should run the same way whether the agent feels creative today or not.
About the Author
I'm Brian Marvin, an AI-native Fractional CTO with 30 years in technical leadership. At empowered.guru, I help startups hand real engineering work to AI agents without losing control of the outcome.